Predictive reasoning
Use predictive reasoning for questions that require a model trained on historical data to make predictions about future or previously unseen events. This overview explains the workflow, helps you decide when predictive reasoning fits, and points you to the right next guide. If you need to control which predictive reasoner PyRel uses, see Configure predictive reasoner settings.
What predictive reasoning is
Section titled “What predictive reasoning is”Predictive reasoning is a workflow for solving prediction problems: questions where the answer is not present in the existing data and must instead be predicted from historical examples.
PyRel offers two independent estimators, both operating directly on your relational data via the same setup:
GNN— a trainable Graph Neural Network. Use it when you have enough labeled data to train a model and want to improve performance through additional training, tuning, and experimentation. It also supports two additional tasks: link prediction and multilabel classification.RelFM— a foundation model that predicts in context, without a training step. Use it when you want to get started quickly, have a small amount of labeled data, or prefer not to manage a training and model-registry lifecycle.
Both estimators work directly with the structure of your relational data. Concepts become node types, relationships between them form the graph’s topology, and column values become node features. You don’t need to flatten your schema into a single wide table or hand-engineer features—the graph preserves the structure that the estimators learn from.
In PyRel, you typically:
- Declare the concepts that participate in the prediction (for example,
Customer,Product,Transaction) and populate them from Snowflake tables. - Define train, validation, and test splits as
selectfragments orrelationshipsover those concepts. - Build a
Graphby adding edges that reflect the foreign-key relationships between concepts. - Configure which properties are features and how to preprocess them with a
PropertyTransformer. - Then either train a
GNNwith.fit()and generate predictions with.predictions(domain=...), or constructRelFMand call.predictions(domain=...)directly — no training step either way requires the other.
The reasoner supports two broad task families:
| Task family | What it predicts | Typical examples | GNN | RelFM |
|---|---|---|---|---|
| Node prediction (binary, multiclass, or multilabel classification, regression) | A categorical label or a numeric value for each entity | Customer churn, smoker status, student interest categories, weekly sales forecasting, review score | ✓ | ✓ (no multilabel) |
| Link prediction (including recurring links) | Whether two entities are, or will be, connected | Next-purchase prediction, post-to-post references, repeat interactions | ✓ | — |
You can read more about the supported task types in the Define a learning task page.
RelFM has a flat-table sibling for non-relational data:
RelFMTabular— the same in-context approach for data that’s already in a single flat table, including forecasting over time-indexed panel data.
When to use predictive reasoning
Section titled “When to use predictive reasoning”Use predictive reasoning when the answer depends on signal spread across multiple related tables, cannot be captured by a fixed rule, join, or formula, and must be inferred rather than directly retrieved from the existing data.
Common scenarios include:
- Customer or subscriber churn. Predict whether a customer will stop engaging based on past transactions, product characteristics, and demographics — for example, churn predicted from a history of purchases, or from review activity.
- Demand and sales forecasting. Predict a numeric outcome per entity from historical events plus entity attributes — for example, weekly sales per store-department, weekly sales per product, or ad click-through rate.
- Next-action and repeat-interaction prediction. Predict which items an entity will interact with next, framed as link prediction between two node types — for example, predicting which products a customer will re-purchase, or which ads a user will click.
- Categorizing entities by their neighborhood. Assign one or more labels to an entity based on the entities it is related to — for example, inferring a student’s subject interests from the classes they take, as a multiclass or multilabel classification task.
Other types of reasoning may be a better fit if:
- Your answer can be derived exactly from existing facts, joins, or aggregations — use rules-based reasoning.
- You need to make a choice subject to constraints, possibly optimizing an objective — use prescriptive reasoning.
- Your question is about graph structure itself — reachability, centrality, or communities — rather than a learned prediction, use graph reasoning.
How the two estimators learn
Section titled “How the two estimators learn”Both estimators see the same graph. What differs is how each uses it to make predictions.
What are GNNs?
Section titled “What are GNNs?”A Graph Neural Network (GNN) is a type of neural network that learns from data organized as a graph — a set of nodes (entities) connected by edges (relationships between them). Unlike a tabular model that sees each row in isolation, a GNN can combine information across many connected rows at once.
The RelationalAI predictive reasoner turns your relational database into a graph automatically:
- Each row of a table becomes a node. A table with 100 rows contributes 100 nodes. All rows from the same table share a node type.
- Foreign-key relationships become edges. When one table references another — for example, a transaction whose
customer_idmatches a customer’scustomer_id— the GNN sees that as an edge between the two corresponding nodes.
Once the graph is built, the GNN learns by combining each node’s attributes with those of its neighbors — a process called message passing — round after round. At every round, each node gathers information from the nodes it’s directly connected to and folds that into its own representation. After several rounds, every node has effectively pulled in signal from increasingly distant neighbors across the graph.
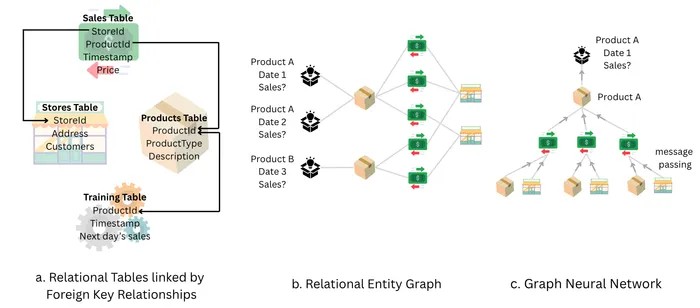
This is how the GNN exploits the relational structure of your data: a customer’s likelihood of churning, for example, depends not just on their own attributes but also on the products they’ve bought, the transactions linking them, and the patterns of other customers connected through those products. Tabular models that see each row in isolation can’t pick up that kind of cross-row signal — GNNs are built to.
The rules that govern how each node combines neighbor information are learned during training by comparing the model’s predictions against known historical outcomes and adjusting until predictions are as accurate as possible.
What is RelFM?
Section titled “What is RelFM?”RelFM is a foundation model that predicts in-context, with no training step. Instead of learning weights from your data, it walks the graph outward from each entity via depth-first search, collecting neighbor rows into a feature table — the same relational signal a GNN would pass via message passing, gathered up front instead of learned over many rounds.
Those features, together with a handful of labeled examples, are then handed to a pretrained in-context model, which predicts directly from the patterns in the examples it’s shown — the same way a large language model completes a pattern from a prompt, without fine-tuning.
Because there’s no fit loop, RelFM has nothing to train, checkpoint, or register: change the data or the labeled examples, and the next .predictions() call reflects the changes immediately. The trade-off is depth — RelFM’s DFS walk has a fixed dfs_max_depth, so it doesn’t propagate signal across arbitrarily many hops the way a multi-round GNN can. RelFM also does not currently support link prediction or multilabel classification. See Predict with RelFM for the full walkthrough.
Where to go next
Section titled “Where to go next”The first three guides apply regardless of which estimator you choose. After that, follow the path for the estimator that best fits your data and workflow—you don’t need to read the other path first.
PropertyTransformer to choose which properties will be fed as features and how to preprocess them.